Unit 5 · 5 teaching hours · 21 min read
Linked Lists
What the syllabus asks for 6
- Singly linked list
- Program: singly linked list
- Linked stack and linked queue
- Doubly and circular linked lists
- Array versus linked list
- Seeing the ideas: nodes, links and pointer changes
A linked list stores each item in a separate node that holds the data and a pointer to the next node. Nodes can sit anywhere in memory; the pointers create the order. Nodes are created with malloc when needed, so the list grows and shrinks as data does.
- The node, the head pointer and the Linked List ADT.
- Insertion and deletion at the beginning, end, and after/before a given node.
- Linked stacks and queues, and the doubly linked list with its advantages.
- A tested program for each, and the pointer-order rules that prevent lost nodes.
5.1 Singly linked list
typedef struct Node { int data; struct Node *next; } Node;
Node *head = NULL;          /* empty list */
head points to the first node; the last node's next is NULL. Losing head loses the whole list.
| Operation | Steps | Cost |
|---|---|---|
| Traverse | for (p = head; p; p = p->next) |
O(n) |
| Insert at beginning | new→next = head; head = new | O(1) |
| Insert at end | walk to last node; last→next = new (O(1) with a tail pointer) | O(n) |
| Insert after node p | new→next = p→next; p→next = new | O(1) |
| Insert before node p | find predecessor q (walk); insert after q | O(n) |
| Delete first | t = head; head = head→next; free(t) | O(1) |
| Delete after p | t = p→next; p→next = t→next; free(t) | O(1) |
| Delete a given node/value | find predecessor; bypass; free | O(n) |
When inserting after p, set new->next = p->next first, then p->next = new. Reversing the order overwrites the only pointer to the rest of the list and the tail is lost (a memory leak and a broken list).
When deleting, remember the node in a temporary pointer before bypassing it, then free it.
List: 10 → 30 → 40. Insert 20 after 10: new(20)→next = 30; node(10)→next = new → 10 → 20 → 30 → 40. Insert 5 at the beginning: new(5)→next = head(10); head = new → 5 → 10 → 20 → 30 → 40.
Delete 30: predecessor is 20; 20→next = 40; free(30) → 5 → 10 → 20 → 40. Delete the head: head = 10, free(5).
5.2 Program: singly linked list
#include <stdio.h>
#include <stdlib.h>

typedef struct Node { int data; struct Node *next; } Node;

Node *new_node(int x) { Node *n = malloc(sizeof *n); n->data = x; n->next = NULL; return n; }

Node *push_front(Node *head, int x) { Node *n = new_node(x); n->next = head; return n; }

Node *push_back(Node *head, int x) {
    Node *n = new_node(x);
    if (!head) return n;
    Node *p = head;
    while (p->next) p = p->next;
    p->next = n;
    return head;
}
void insert_after(Node *p, int x) { Node *n = new_node(x); n->next = p->next; p->next = n; }

Node *delete_value(Node *head, int x) {
    Node *prev = NULL, *p = head;
    while (p && p->data != x) { prev = p; p = p->next; }
    if (!p) { printf("%d not found\n", x); return head; }
    if (prev) prev->next = p->next; else head = p->next;
    free(p);
    return head;
}
Node *reverse(Node *head) {
    Node *prev = NULL, *cur = head;
    while (cur) { Node *nxt = cur->next; cur->next = prev; prev = cur; cur = nxt; }
    return prev;
}
void print(const char *msg, Node *head) {
    printf("%-20s", msg);
    for (Node *p = head; p; p = p->next) printf("%d -> ", p->data);
    printf("NULL\n");
}

int main(void) {
    Node *h = NULL;
    h = push_back(h, 10); h = push_back(h, 30); h = push_back(h, 40);
    print("start:", h);
    insert_after(h, 20);       print("insert 20 after 10:", h);
    h = push_front(h, 5);      print("insert 5 at front:", h);
    h = delete_value(h, 30);   print("delete 30:", h);
    h = delete_value(h, 99);
    h = delete_value(h, 5);    print("delete head 5:", h);
    h = reverse(h);            print("reversed:", h);
    while (h) h = delete_value(h, h->data);   /* free everything */
    return 0;
}
start:              10 -> 30 -> 40 -> NULL
insert 20 after 10: 10 -> 20 -> 30 -> 40 -> NULL
insert 5 at front:  5 -> 10 -> 20 -> 30 -> 40 -> NULL
delete 30:          5 -> 10 -> 20 -> 40 -> NULL
99 not found
delete head 5:      10 -> 20 -> 40 -> NULL
reversed:           40 -> 20 -> 10 -> NULL
5.3 Linked stack and linked queue
Linked stack. Push = insert at the beginning, pop = delete from the beginning; the head is the top. Both O(1), and there is no fixed capacity, so no overflow except running out of memory.
Linked queue. Keep front (head) and rear (tail) pointers. Enqueue: link a new node after rear and move rear. Dequeue: remove at front. If the queue becomes empty set both to NULL. Both operations are O(1), fixing the O(n) problem of the array-list queue in Unit 4.
#include <stdio.h>
#include <stdlib.h>

typedef struct N { int d; struct N *next; } N;

/* linked stack */
N *spush(N *top, int x) { N *n = malloc(sizeof *n); n->d = x; n->next = top; return n; }
N *spop(N *top, int *x) { N *t = top; *x = t->d; top = t->next; free(t); return top; }

/* linked queue */
typedef struct { N *front, *rear; } Q;
void enq(Q *q, int x) {
    N *n = malloc(sizeof *n); n->d = x; n->next = NULL;
    if (q->rear) q->rear->next = n; else q->front = n;
    q->rear = n;
}
int deq(Q *q) {
    N *t = q->front; int x = t->d;
    q->front = t->next; if (!q->front) q->rear = NULL;
    free(t); return x;
}

int main(void) {
    N *s = NULL; int v;
    for (int i = 1; i <= 4; i++) s = spush(s, i * i);
    printf("stack pops:");
    while (s) { s = spop(s, &v); printf(" %d", v); }
    Q q = {NULL, NULL};
    for (int i = 1; i <= 4; i++) enq(&q, i * i);
    printf("\nqueue deqs:");
    while (q.front) printf(" %d", deq(&q));
    printf("\n");
    return 0;
}
stack pops: 16 9 4 1
queue deqs: 1 4 9 16
5.4 Doubly and circular linked lists
A doubly linked list node has two pointers, prev and next:
typedef struct DNode { int data; struct DNode *prev, *next; } DNode;
Advantages over a singly linked list
- Traversal in both directions.
- A node can be deleted given only a pointer to it:
p->prev->next = p->next; p->next->prev = p->prev;(O(1), no predecessor search). - Insertion before a node is O(1).
- Easier to implement deques, undo histories and browser history.
Disadvantages: an extra pointer per node, and every update changes four pointers instead of two.
Insert new node n after p: n->next = p->next; n->prev = p; if (p->next) p->next->prev = n; p->next = n;
A circular linked list makes the last node point to the first; there is no NULL. It suits round-robin scheduling, where the CPU cycles through the same processes forever. Traversal must stop when it returns to the starting node.
#include <stdio.h>
#include <stdlib.h>

typedef struct D { int data; struct D *prev, *next; } D;

D *mk(int x) { D *n = malloc(sizeof *n); n->data = x; n->prev = n->next = NULL; return n; }

void insert_after(D *p, int x) {
    D *n = mk(x);
    n->next = p->next; n->prev = p;
    if (p->next) p->next->prev = n;
    p->next = n;
}
D *remove_node(D *head, D *p) {                 /* delete using only a pointer to the node */
    if (p->prev) p->prev->next = p->next; else head = p->next;
    if (p->next) p->next->prev = p->prev;
    free(p);
    return head;
}
void forward(D *h)  { for (; h; h = h->next) printf("%d ", h->data); printf("\n"); }
void backward(D *h) { while (h->next) h = h->next; for (; h; h = h->prev) printf("%d ", h->data); printf("\n"); }

int main(void) {
    D *head = mk(10);
    insert_after(head, 30);
    insert_after(head, 20);                  /* 10 20 30 */
    insert_after(head->next->next, 40);      /* 10 20 30 40 */
    printf("forward : "); forward(head);
    printf("backward: "); backward(head);
    head = remove_node(head, head->next);    /* delete 20 */
    printf("after deleting 20: "); forward(head);
    head = remove_node(head, head);          /* delete the head */
    printf("after deleting head: "); forward(head);
    return 0;
}
forward : 10 20 30 40
backward: 40 30 20 10
after deleting 20: 10 30 40
after deleting head: 30 40
5.5 Array versus linked list
| Array | Linked list | |
|---|---|---|
| Indexing | O(1) | O(n) |
| Insert/delete at front | O(n) | O(1) |
| Insert/delete after a known node | O(n) | O(1) |
| Memory per item | data only | data + 1 or 2 pointers |
| Cache behaviour | excellent | poor |
| Size | fixed or reallocated | dynamic |
5.6 Seeing the ideas: nodes, links and pointer changes
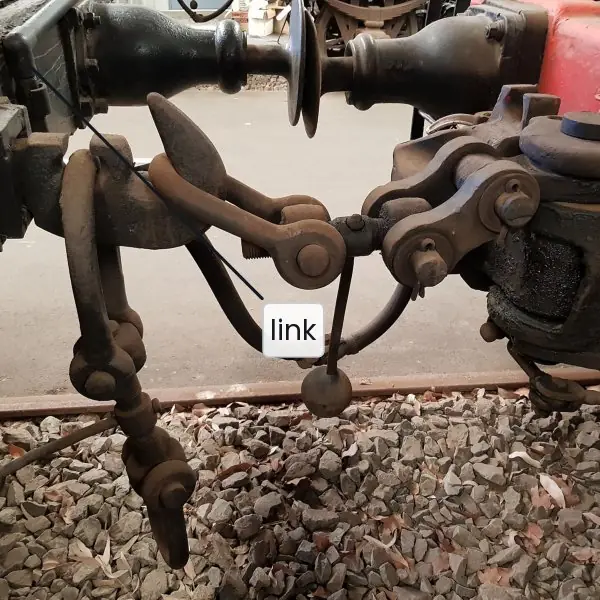
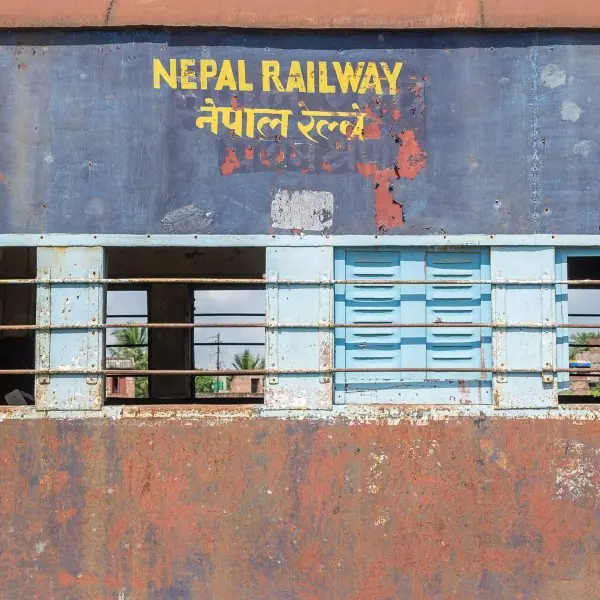
A linked list is a train. Each coach carries its own load and is coupled to the next coach; to add a coach you uncouple one link and couple two, and no other coach has to move.
The photographs show the real objects behind the picture: the chain-and-hook coupling between two railway wagons, and a coach of Nepal Railway at Janakpur, a line whose coaches were joined in exactly this way.


5.6.1 Eight advantages of the linked list
- The size is dynamic. A linked list asks for memory one node at a time with
malloc, so it grows and shrinks while the program runs. The programmer need not guess a maximum size, as with an array. A list of customers in a Nepali shop can therefore grow from five to five thousand without any change in the code. - Insertion is cheap. Adding a node needs only two pointer changes, as Figure 5.1 shows, and no item is shifted. In an array the same insertion may move thousands of items. This makes linked lists excellent for data that change often.
- Deletion is cheap. Removing a node means making the previous node point past it and then freeing it (Figure 5.2). The other nodes stay where they are in memory. The cost is O(1) after the node has been located.
- There is no wasted space. Memory is used only for the nodes that exist, plus one pointer each. An array of 10,000 cells reserved for a class of 60 students wastes the rest. A list of 60 nodes uses exactly 60 nodes.
- Nodes need not be contiguous. The nodes may be scattered anywhere in memory, joined by pointers. A big list can therefore be built even when memory is fragmented and no large free block exists. This matters on small systems such as microcontrollers.
- Other structures are easy to build. Stacks, queues, deques, hash-table chains, adjacency lists of graphs and polynomials are all naturally made of linked lists. The linked stack and linked queue of Section 5.3 never overflow while memory remains. One structure therefore supports many others.
- Variants add power. A doubly linked list can be walked in both directions and a node can delete itself. A circular list suits round-robin scheduling and repeating playlists. The same idea thus adapts to different jobs.
- Efficient memory re-use. Freed nodes return to the system and can be used by other parts of the program. A long-running server, such as the one behind a payment system, can keep its memory use steady. This is not possible with a fixed-size array that must be reserved for the worst case.


Formula and fact sheet
- Node = data +
next(+prev).head == NULLmeans empty. - Insert after p: new→next = p→next, then p→next = new.
- Delete after p: save t = p→next; p→next = t→next; free(t).
- Linked stack/queue operations are O(1); queue needs a rear pointer.
- Doubly linked: both directions, O(1) delete of a known node, extra memory.
- Circular: last node points to first; stop traversal on returning to the start.
Chapter summary
- Linked lists trade O(1) indexing for O(1) structural change and dynamic size.
- The order of pointer assignments is the main source of bugs; always free removed nodes.
- Stacks and queues become capacity-free and O(1) when linked.
- Doubly linked lists add back-links for flexible deletion and two-way traversal.
Practice
- Define linked list. Why is it called dynamic?
- List 7 → 9 → 15. Show the pointer changes for: insert 8 after 7, insert 3 at the front, delete 9.
- Write C code to count the nodes of a singly linked list.
- Write the steps to insert a node before a given node p in a singly linked list. Why is it O(n)?
- Implement a linked stack's push and pop; explain why overflow does not occur.
- State three advantages and two disadvantages of a doubly linked list.
- Write the pointer statements to delete node p from a doubly linked list.
- Explain how to reverse a singly linked list in place.
- Compare an array and a linked list for a queue implementation.
Answers and worked solutions
1. A collection of nodes each pointing to the next. Nodes are allocated and freed at run time, so size follows the data.
2. insert 8 after 7: new(8)→next = 9; node(7)→next = new → 7, 8, 9, 15. Insert 3 at front: new(3)→next = head(7); head = new → 3, 7, 8, 9, 15. Delete 9: predecessor 8; 8→next = 15; free(9) → 3, 7, 8, 15.
3. int count(Node *h){ int c = 0; for (; h; h = h->next) c++; return c; }
4. Walk from head to the node q whose next is p (O(n)); then n->next = p; q->next = n;. If p is the head, set n->next = head; head = n. The walk is needed because a singly linked node has no pointer back to its predecessor.
5. Push: n->next = top; top = n. Pop: t = top; top = top->next; free(t). Nodes are allocated one at a time, so the stack is never "full" except when malloc fails.
6. Advantages: two-way traversal; O(1) delete given the node; O(1) insert before a node. Disadvantages: extra pointer per node; more pointer updates per operation.
7. if (p->prev) p->prev->next = p->next; else head = p->next; if (p->next) p->next->prev = p->prev; free(p);
8. Walk with three pointers (prev, cur, nxt): save nxt = cur->next, set cur->next = prev, advance prev = cur, cur = nxt; when finished head = prev. O(n) time, O(1) space.
9. Array: fixed capacity, circular logic needed, no pointer overhead. Linked: unlimited capacity, simple O(1) enqueue/dequeue using front and rear pointers, one pointer of overhead per item and a malloc/free per operation.
Model answers (5 and 10 marks)
Q1. What is a singly linked list? Write the node structure and the algorithm to insert a node at the beginning. (5 marks)
A singly linked list is a dynamic linear data structure made of nodes. Each node stores a data item and a pointer next to the following node; the first node is reached through a pointer head, and the last node's next is NULL.
The nodes need not be adjacent in memory (Plate 5.1).
struct node {
    int data;
    struct node *next;
};
struct node *head = NULL;
Insertion at the beginning.
- Allocate a new node:
new = malloc(sizeof(struct node)); if it returnsNULL, report that memory is exhausted and stop. - Store the value:
new->data = x. - Link it to the old list:
new->next = head. - Make it the first node:
head = new.
The order of steps 3 and 4 is important (Figure 5.1a): if head were changed first, the address of the old first node would be lost. The operation needs no loop, so its time is O(1).
For an empty list head is NULL, so the new node becomes the only node and its next is NULL. Insertion at the end needs a walk to the last node, O(n), unless a tail pointer is kept.
Q2. Differentiate between an array and a linked list. (5 marks)
An array keeps its items in one block of consecutive memory; a linked list keeps each item in a separate node joined by pointers.
| Point | Array | Linked list |
|---|---|---|
| Memory allocation | static, fixed in advance | dynamic, node by node |
| Access to i-th item | direct, O(1) | walk i nodes, O(n) |
| Insert / delete in the middle | O(n) shifting | O(1) after locating the node |
| Memory use | wasted if oversized, overflow if undersized | one pointer extra per node, no waste |
| Search | O(n); O(\log n) by binary search if sorted | O(n); binary search is not possible |
| Memory layout | contiguous, good cache speed | scattered, slower |
Use an array when the size is known and items are read by position, for example the marks of 60 students.
Use a linked list when the size changes and insertions and deletions dominate, for example a task list or the chains of a hash table. Binary search is not possible on a linked list because the middle node cannot be reached directly.
Q3. Explain the operations on a singly linked list with algorithms, and describe the doubly and circular linked lists. (10 marks)
Introduction. A linked list stores items in nodes; the pointer head gives access to the whole list. Its operations are traversal, insertion, deletion and search, and each of them works by following or changing next pointers.
Traversal. Set p = head; while p != NULL, process p->data and set p = p->next. Time O(n).
Insertion.
At the beginning new->next = head; head = new; (O(1)).
After a given node B new->next = B->next; B->next = new; (O(1), Figure 5.1b).
At the end walk to the last node last and set last->next = new; new->next = NULL; (O(n)).
Deletion.
First node temp = head; head = head->next; free(temp); (O(1)).
Node after A temp = A->next; A->next = temp->next; free(temp); (O(1)).
Last node walk to the second-last node, set its next to NULL and free the last (O(n)). The link must be changed before the node is freed (Figure 5.2a).
Search. Walk from head comparing p->data with the key until found or NULL is reached. O(n).
Doubly linked list. Each node has prev, data and next. It can be traversed forwards and backwards and a node can be deleted when only its own address is known by p->prev->next = p->next; p->next->prev = p->prev;.
The cost is one more pointer per node and four pointer changes for an insertion (Figure 5.2b).
Circular linked list. The last node points to the first, so there is no NULL; traversal stops when the pointer returns to the start (Figure 5.2c). It suits round-robin scheduling and repeating playlists.
| Type | Pointers per node | Traversal | Delete a given node | Use |
|---|---|---|---|---|
| Singly | 1 | forward only | needs the previous node | stacks, queues |
| Doubly | 2 | both ways | O(1) | browser history, editors |
| Circular | 1 (or 2) | loops forever | needs the previous node | schedulers, playlists |
Conclusion. Linked lists trade direct access for flexible size and cheap insertion and deletion. Understanding pointer order, such as setting new->next before moving head, is the key to writing them without losing nodes.