Unit 3 · 7 teaching hours · 15 min read
Cloud Storage, Erasure Coding, Consistent Hashing and Quorums
What the syllabus asks for 6
- Three kinds of cloud storage
- Replication versus erasure coding
- Consistent hashing
- Replication and quorums
- Seeing the ideas: storage media, erasure coding, the hash ring and quorums
- Summary and exercises
When a cloud provider advertises "eleven nines" of durability for stored objects, nobody is claiming that disks never fail. Disks fail constantly.
The claim rests on mathematics: spreading data so that several simultaneous failures are needed to lose any of it, and repairing faster than failures accumulate.
This unit shows the three tools that make that possible: erasure coding (cheap redundancy), consistent hashing (spreading data across a changing set of machines) and quorums (agreeing on reads and writes across replicas).
- Object, block and file storage and when each fits.
- Replication versus Reed-Solomon erasure coding: overhead and durability calculations.
- Consistent hashing with virtual nodes, executed and measured.
- Quorum rule R + W > N, verified by brute force.
3.1 Three kinds of cloud storage
| Type | Interface | Typical service | Best for |
|---|---|---|---|
| Object | HTTP API (PUT, GET by key) on flat buckets | Amazon S3, Azure Blob, Google Cloud Storage | Media, backups, data lakes, static websites |
| Block | Raw volume attached to one VM, like a disk | Amazon EBS, Azure Disk | Databases, boot volumes |
| File | POSIX or SMB shared file system | Amazon EFS, Azure Files | Shared content, legacy applications |
Object storage trades POSIX semantics (no in-place partial update, no directories as real objects) for near-unlimited scale and very high durability. It is the base layer on which most cloud data systems are built.
Storage is also tiered by access frequency (hot, infrequent-access, archive), with lower per-GB prices and higher retrieval costs for colder tiers.
3.2 Replication versus erasure coding
Replication keeps n full copies. It is simple and fast to read, but a 3-way scheme stores three bytes for every byte of data (overhead 3×).
Erasure coding splits an object into k data shards and computes m parity shards, giving n = k + m shards on different failure domains.
In a Reed-Solomon code, arithmetic is done over a Galois field (commonly GF(2⁸)), and any k of the n shards reconstruct the object. The code therefore tolerates the loss of any m shards at a storage overhead of (k + m) ÷ k.
RS(10,4) stores 14 shards per 10 of data, an overhead of 1.4×, yet survives four losses; 3-way replication survives two with an overhead of 3×.
The price is repair and read cost: reconstructing one lost shard means reading k other shards across the network (ten times the shard size for RS(10,4)), and the encode and decode work consumes CPU. Hot data often stays replicated while colder data is erasure coded.
Durability arithmetic
Assume each shard is independently lost within a repair window with probability p and that data is lost if more than m of the n shards fail:
P(loss) = Σ over i from m+1 to n of C(n, i) · pⁱ · (1 − p)ⁿ⁻ⁱ
from math import comb

def p_loss(n, m, p):
    return sum(comb(n, i) * p**i * (1 - p)**(n - i) for i in range(m + 1, n + 1))

p = 0.01
for name, n, m in (("3x replication", 3, 2), ("RS(10,4)", 14, 4), ("RS(6,3)", 9, 3)):
    k = n - m
    print(f"{name}: overhead {n / k:.2f}x, P(loss) {p_loss(n, m, p):.3e}")
3x replication: overhead 3.00x, P(loss) 1.000e-06
RS(10,4): overhead 1.40x, P(loss) 1.857e-07
RS(6,3): overhead 1.50x, P(loss) 1.210e-06
With a 1% per-window failure chance, 3-way replication loses data with probability 1.000e-06, but RS(10,4) reaches 1.857e-07 at less than half the storage overhead.
RS(6,3) shows the other side of the trade: 1.5× overhead with similar durability to replication.
Real providers also correlate failures (a rack, a power feed, a bad firmware batch), so shards go to different failure domains and the independence assumption is applied only within that separation.
The formula assumes independent failures. Correlated failures dominate real loss events, so quoted nines are design targets, not guarantees; the service-level agreement, not the durability figure, is what the provider is contractually bound to (Unit 7).
3.3 Consistent hashing
To spread keys across many storage nodes, the naive rule node = hash(key) mod N fails when N changes: adding one node to three remaps about N ÷ (N+1) = 75% of the keys, forcing a data shuffle.
Consistent hashing (Karger et al., 1997) maps both nodes and keys onto the same circular space (for example, 0 to 2³²−1). A key belongs to the first node clockwise from its position.
Adding or removing a node therefore moves only the keys in the arc next to it, about 1 ÷ (N+1) of the total. Dynamo, Cassandra and many CDNs use this idea.
With only a few points per node the arcs are uneven, so each physical node is hashed to many virtual nodes (vnodes), which smooths the load and spreads a failed node's keys among many survivors.
import hashlib, bisect

def H(s):
    return int(hashlib.sha256(s.encode()).hexdigest()[:8], 16)

def build(nodes, vnodes=200):
    return sorted((H(f"{n}#{i}"), n) for n in nodes for i in range(vnodes))

def lookup(ring, key):
    i = bisect.bisect_left(ring, (H(key), ""))
    return ring[i % len(ring)][1]

ring3, ring4 = build("ABC"), build("ABCD")
keys = [f"key{i}" for i in range(1000)]
moved = [k for k in keys if lookup(ring3, k) != lookup(ring4, k)]
print(f"adding node D moved {len(moved)} of 1000 keys (ideal 250)")
print(f"all moved keys went to D: {all(lookup(ring4, k) == 'D' for k in moved)}")
adding node D moved 214 of 1000 keys (ideal 250)
all moved keys went to D: True
Only 214 of 1,000 keys moved, against an ideal of 250 (the gap is sampling variance; it narrows with more vnodes and more keys), compared with about 750 for mod-N hashing.
Every moved key landed on the new node D: nothing shuffled between old nodes, which is the key property.
3.4 Replication and quorums
Dynamo-style systems keep N replicas of each key. A write is acknowledged after W replicas confirm, and a read consults R replicas, returning the newest version (by version number or vector clock).
If R + W > N, every read set overlaps every write set in at least one replica, so a read always sees the latest acknowledged write.
from itertools import combinations
for n, w, r in ((3, 2, 2), (3, 1, 1), (5, 3, 3), (5, 2, 3)):
    ok = all(set(a) & set(b) for a in combinations(range(n), w) for b in combinations(range(n), r))
    print(f"N={n} W={w} R={r}: R+W>N is {r + w > n}, every read set meets every write set: {ok}")
N=3 W=2 R=2: R+W>N is True, every read set meets every write set: True
N=3 W=1 R=1: R+W>N is False, every read set meets every write set: False
N=5 W=3 R=3: R+W>N is True, every read set meets every write set: True
N=5 W=2 R=3: R+W>N is False, every read set meets every write set: False
Brute force over every pair of subsets agrees with the inequality in all four cases. N=3, W=2, R=2 tolerates one replica failure for both reads and writes; N=3 with W=R=1 is fast but can return stale data; N=5, W=2, R=3 sums to exactly N and so fails the rule.
For a read-heavy catalogue, choose W=N and R=1: reads are cheap, writes need every replica. For a write-heavy log choose W=1 and R=N. A balanced R=W=⌈(N+1)/2⌉ gives the highest tolerance for failures.
Quorums do not give full linearizability by themselves (concurrent writes, sloppy quorums with hinted handoff, and clock issues complicate matters), but they give the tunable consistency that the CAP theorem and its refinement PACELC describe: during a partition, choose consistency or availability; otherwise, choose latency or consistency.
Cloud object stores today (such as S3) offer strong read-after-write consistency for single objects, while many NoSQL services still let you choose.
3.5 Seeing the ideas: storage media, erasure coding, the hash ring and quorums
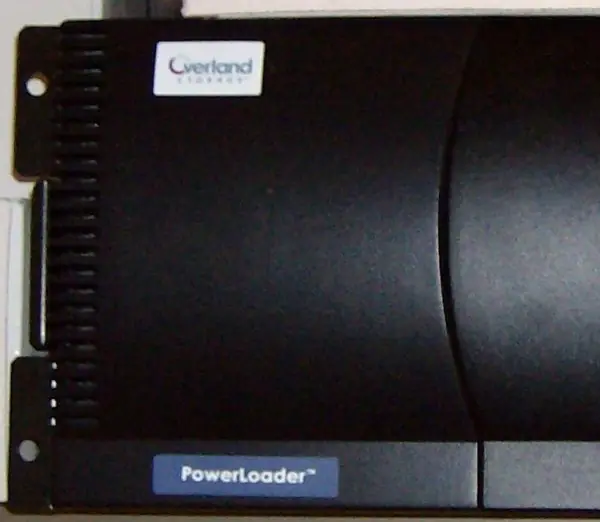
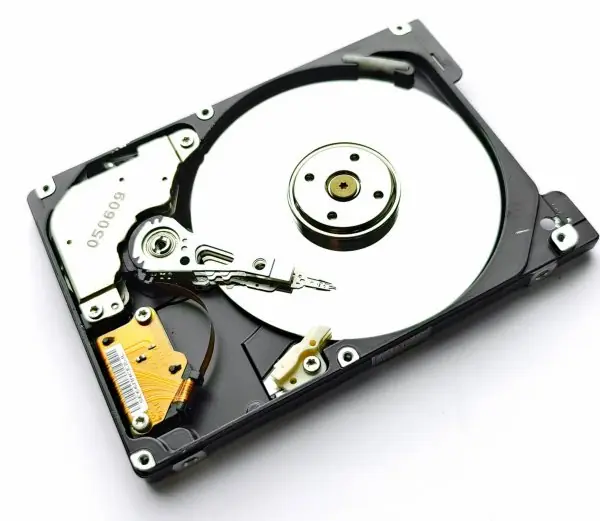
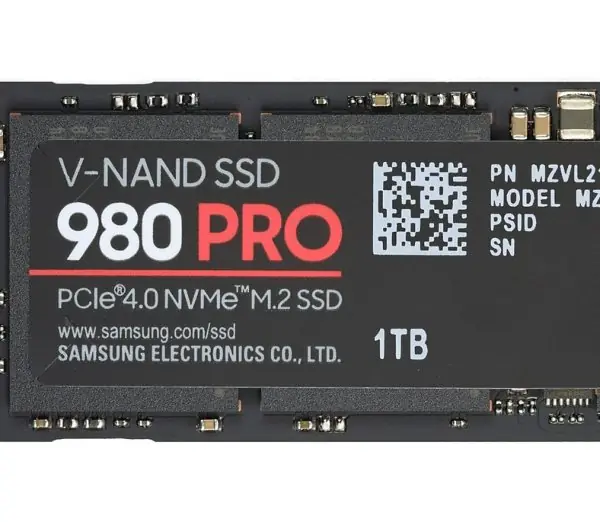
Cloud storage sits on very ordinary media. Plate 3.1 shows the three that matter: archival tape, spinning disk and flash. The provider mixes them into the hot, infrequent and archive tiers of section 3.1.


3.5.1 Eight features of cloud object storage
- Near-unlimited scale. A bucket can hold billions of objects without the owner planning disk space. A national exam board can keep millions of scanned answer sheets in one place. The provider adds hardware behind the scenes.
- Very high durability. Data is copied or erasure coded across several disks, racks and zones, so quoted durability is eleven nines. The chance of losing a stored object in a year is tiny. This is far safer than a single office hard disk.
- Simple HTTP interface. Objects are written and read by key with PUT and GET over HTTPS. Any language and any device can use the same API. A mobile app in Nepal can upload a photo directly to storage.
- Pay for what is stored. Billing is per gigabyte-month plus requests and transfer. A small NGO pays for a few gigabytes, not a whole disk array. Costs fall further when old data moves to colder tiers.
- Storage tiers. Hot, infrequent-access and archive tiers trade price against retrieval speed. Tax records needed once a year can sit in archive at a fraction of the cost. Lifecycle rules move data automatically.
- Versioning and recovery. Versioning keeps old copies of an object after overwrite or delete. A staff member who deletes a report by mistake can restore the earlier version. This also helps against ransomware.
- Access control and encryption. Each bucket has policies, and data is encrypted at rest and in transit. Pre-signed links give temporary access to one file. A college can share a result PDF for one day only.
- Static website and CDN hosting. A bucket can serve HTML, images and video directly, and a CDN caches them near users. A news site can survive a traffic spike without extra servers. Hosting costs stay very low.
3.6 Summary and exercises
Object, block and file storage serve different access patterns; erasure coding gives high durability at low overhead at the cost of repair traffic; consistent hashing with vnodes localises data movement when nodes join or leave; and quorums with R + W > N give read-your-latest-write behaviour.
- Compare object, block and file storage and match each with a workload.
- Compute the storage overhead of RS(12,4) and RS(8,2), and state how many failures each tolerates.
- For n = 5, m = 2 and p = 0.02 write the P(loss) expression and evaluate it.
- Why does
hash mod Nremap most keys when N changes, and consistent hashing does not? - Explain why vnodes improve load balance.
- Is N=4, W=2, R=3 a strict quorum? What about N=4, W=2, R=2?
Model answers: medium (5 marks) and long (10 marks) questions
Q1 (5 marks). Distinguish object, block and file storage in the cloud.
Introduction. Cloud providers offer three storage interfaces because applications need different things from a disk (section 3.1).
| Point | Object | Block | File |
|---|---|---|---|
| Unit | Object with key and metadata | Fixed-size blocks | Files in folders |
| Access | HTTP API (PUT/GET) | Attached to one VM as a disk | NFS or SMB share |
| Scale | Near-unlimited | Limited per volume (TBs) | Large, shared |
| Latency | Higher (tens of ms) | Lowest | Medium |
| Examples | Amazon S3, Azure Blob | Amazon EBS | Amazon EFS |
| Best for | Backups, media, data lakes, static sites | Databases, boot disks | Shared content, legacy apps |
Example. A hospital keeps scanned reports in object storage, its patient database on a block volume and shared department documents on a file share.
Conclusion object storage is cheapest and most scalable, block is fastest for databases, and file storage supports shared legacy software.
Q2 (5 marks). Explain erasure coding with an example and compare it with replication.
Idea. An object is cut into k data shards and m parity shards are computed with a Reed-Solomon code; the n = k + m shards go to different failure domains, and any k of them rebuild the object (Figure 3.1).
Example. RS(4,2) gives 6 shards for 4 units of data: overhead 6/4 = 1.5x, and any two shards can be lost. 3-way replication also survives two losses but costs 3x.
For 100 TB of data the replicated system needs 300 TB and the coded one 150 TB, so 150 TB (50 percent) is saved.
| Point | Replication | Erasure coding |
|---|---|---|
| Overhead | n times (3x) | (k+m)/k (1.4x to 1.5x) |
| Read | Fast, one copy | Needs k shards when degraded |
| Repair | Copy one replica | Read k shards, compute |
| CPU use | Low | Higher |
| Used for | Hot data | Warm and cold data |
Conclusion: erasure coding gives equal durability at much lower space, at the price of repair traffic and CPU.
Q3 (10 marks). Explain how a distributed cloud store distributes and replicates data. Describe consistent hashing and quorum replication, with the durability trade-off between replication and erasure coding.
Introduction. A cloud object store such as S3 must keep trillions of objects on thousands of servers that fail every day.
Three questions arise: where does an object live, how many copies exist, and how does a reader get the latest value? Plate 3.1 shows the media; the algorithms are below.
Placement: consistent hashing. With simple modulo placement (server = hash(key) mod N), adding one server remaps almost all keys.
In consistent hashing servers and keys are hashed onto one ring; a key is stored on the first server clockwise from its hash (Figure 3.2). Adding or removing a server moves only the keys in one arc, about 1/N of the data.
Real systems give each server many virtual nodes on the ring so that load is spread evenly and a failed server's load is shared by many.
Replication and quorums. Each key is stored on N consecutive servers on the ring (commonly N = 3). A write succeeds when W replicas acknowledge, and a read consults R replicas.
If R + W > N, the read set and write set overlap, so the reader sees the latest value (Figure 3.3).
N=3, W=2, R=2 tolerates one slow or failed replica; W=1 gives fast writes with weaker consistency; W=N gives strong writes that fail when any replica is down. This is the CAP trade-off in practice.
Durability. Replication stores n full copies; erasure coding stores k+m shards (Figure 3.1). If each shard is lost within a repair window with probability p = 0.01, data is lost when more than m of n shards fail.
The book's program gives P(loss) = 1.0e-06 for 3x replication (overhead 3.00x), 1.86e-07 for RS(10,4) (1.40x) and 1.21e-06 for RS(6,3) (1.50x). RS(10,4) therefore stores less than half the bytes and is also safer.
Failures are really correlated (rack, power), so shards are spread across failure domains.
| Point | Replication | Erasure coding |
|---|---|---|
| Space overhead | 3.0x | 1.4x to 1.5x |
| Durability (p = 0.01) | 1.0e-06 | 1.9e-07 (RS 10,4) |
| Repair cost | Low | High |
| Best tier | Hot | Cold and warm |
Conclusion. Consistent hashing places data with minimal movement, quorums balance consistency against availability, and erasure coding buys durability cheaply. Together with tiering (Plate 3.1) they let providers offer eleven-nines durability at low prices.